Under review at ICLR 2027
DepGraph-U: Dependency-Aware Execution Pruning for Unified Multimodal Inference
Abstract
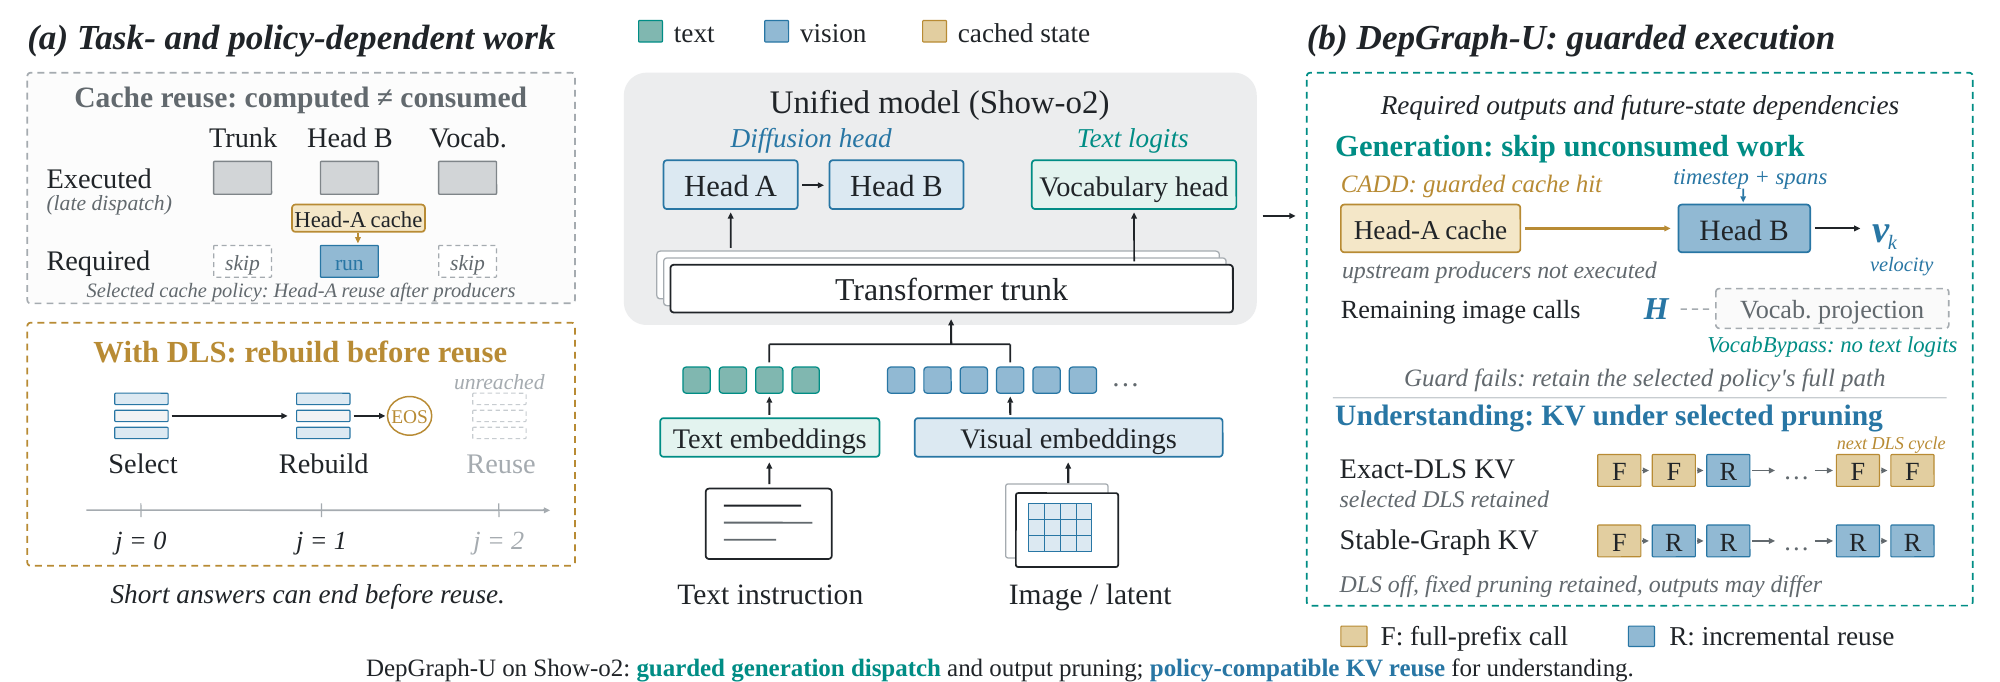
Unified multimodal models (UMMs) bring understanding and generation into a single Transformer, reducing the need for separate specialist models. A shared inference implementation can nevertheless execute operators that the current request does not consume. Even when a valid image cache exists, or a caller requests pixels rather than text, unused producers and vocabulary projections can still execute. We use output-dependent liveness to identify work that remains executable but is unnecessary for the requested output or required future state. To address this, we propose DepGraph-U, a dependency-aware execution framework that uses audited output and state dependencies to guide guarded inference rewrites, without further weight modification. Cache-Aware Dependency Dispatch (CADD) bypasses upstream producers on safe cache hits, and an image-only interface omits unused vocabulary projection. For understanding, graph-compatible KV policies distinguish preserving dynamic layer selection from enabling earlier reuse under a stable graph. We evaluate DepGraph-U across two Show-o2 scales and eight benchmarks. The complete system achieves 2.88–3.21× generation speedup over native Show-o2, with quality trade-offs from the selected approximation policies. Against the reconstructed understanding reference, Exact-DLS preserves all 24,769 decoded responses with 1.15–2.34× speedup. Across the six tested understanding tasks, 80.8% of Exact-DLS examples finish before incremental reuse, explaining why cache compatibility alone does not determine realized latency.
Method overview
The PDF is the submitted manuscript. For updated MMStar metrics, see the metric correction.